
Higgsfield Takes AI Video From 1 Minute to Over 10
Short clips have been the defining constraint of AI video. Most generators cap out in seconds; even ambitious tools usually stop around a minute. Higgsfield says it has pushed past that ceiling — from roughly one minute to over 10 minutes of continuous output. If that holds, it's the biggest change to AI video in a year.
The change comes from an OpenAI customer story published this week, and it's a useful look at where long-form AI video is heading. It's also a claim worth reading carefully — vendor AI video announcements tend to be ahead of independent testing.
What Higgsfield Actually Changed
According to OpenAI's account, Higgsfield built a GPT-6 Astra-based workflow that generates instructional videos longer than 10 minutes for its YouTube channel. Higgsfield CEO and co-founder Alex Mashrabov said the earlier process topped out at roughly one minute per generation.
The practical shift is what matters: longer output means no manual stitching for medium-form content. Instead of assembling a dozen short clips in an editor, a team can produce one continuous AI video — at least according to the companies involved.
Mashrabov frames the capability as a single creator running an entire high-end production start to finish, rather than a team assembling fragments. That's the promise of long-form AI video: fewer handoffs, fewer seams.
The Model Stack Behind It
Higgsfield's workflow pairs generation with orchestration. Per OpenAI, that involves two systems, and together they show how a modern AI video pipeline is assembled:
- GPT-6 Astra — powers the AI video generation and runs the creative agents that automate repetitive production work, such as generating multiple shot variations.
- Tool calling — GPT-6 Astra lets those agents call external tools for complex manual tasks, including 3D modeling.
The 3D modeling detail is the interesting one. Mashrabov connects tool use directly to consistency: when the same underlying scene geometry can be referenced repeatedly, the model has a stable anchor instead of reinventing the world on every shot. That's the kind of plumbing long AI video needs.
A second model, GPT-Image-2.5, is reported to handle precise visual control — the layer that keeps characters and styling from drifting across a long AI video. Together they form a stack rather than a single generator, which is what separates this AI video workflow from a one-shot clip tool.
Why Consistency Was the Real Barrier
Length alone was never the hard problem. Continuity was. A 10-second AI video can hide almost any inconsistency; a 10-minute one cannot.
Faces shift, wardrobes change, rooms rearrange themselves, and lighting drifts between shots. Viewers forgive that in a meme clip and abandon a tutorial over it. That's why long-form AI video has lagged behind short-form even as single-clip quality improved dramatically. Every serious AI video roadmap runs into the same wall.
Higgsfield's approach — agents plus external tools plus a control layer — is essentially an attempt to keep the world stable across many generations. If it works, the unlock isn't just duration; it's the format.
Read This Claim With Care
Here's the part most coverage skips. The Higgsfield numbers come from OpenAI and Higgsfield themselves. As Data Phoenix noted in its analysis, the account includes no independent benchmarks of output quality, production time, cost, or required human intervention.
The source also doesn't clarify whether a finished 10-minute AI video is a single model generation or an orchestration of many shorter pieces stitched by tooling. Those are very different claims, and they matter for anyone planning a workflow built on AI video.
Treat the 10-minute figure as vendor-reported capability until independent testing appears. That's not a reason to dismiss it — it's a reason to verify before you rebuild your pipeline around it. Skepticism about an AI video claim costs nothing; rebuilding a pipeline around a wrong one costs a lot. And if the AI video number holds up, the whole medium-form category changes.
What It Means for Creators
Three takeaways stand out for anyone working with AI video:
- Continuity is the frontier — the next differentiator isn't clip length but cross-shot stability.
- Orchestration beats one-shot — agents, tools, and reference layers are how long AI video gets made.
- Vendor numbers need verification — always test the claim on your own content before trusting it.
- Medium-form is now plausible — explainers, tutorials, and training content are the formats most affected.
The realistic near-term impact is on instructional and educational AI video, not cinema. That's still a large and underserved category, and it's where AI video can win on economics before it wins on artistry.
A Prompt to Try Today
Consistency starts with a clear, repeatable visual description — the same discipline any long AI video depends on. Try this on Fanch AI:
Copy & Paste this into Fanch AI (Model: gpt_image_2):
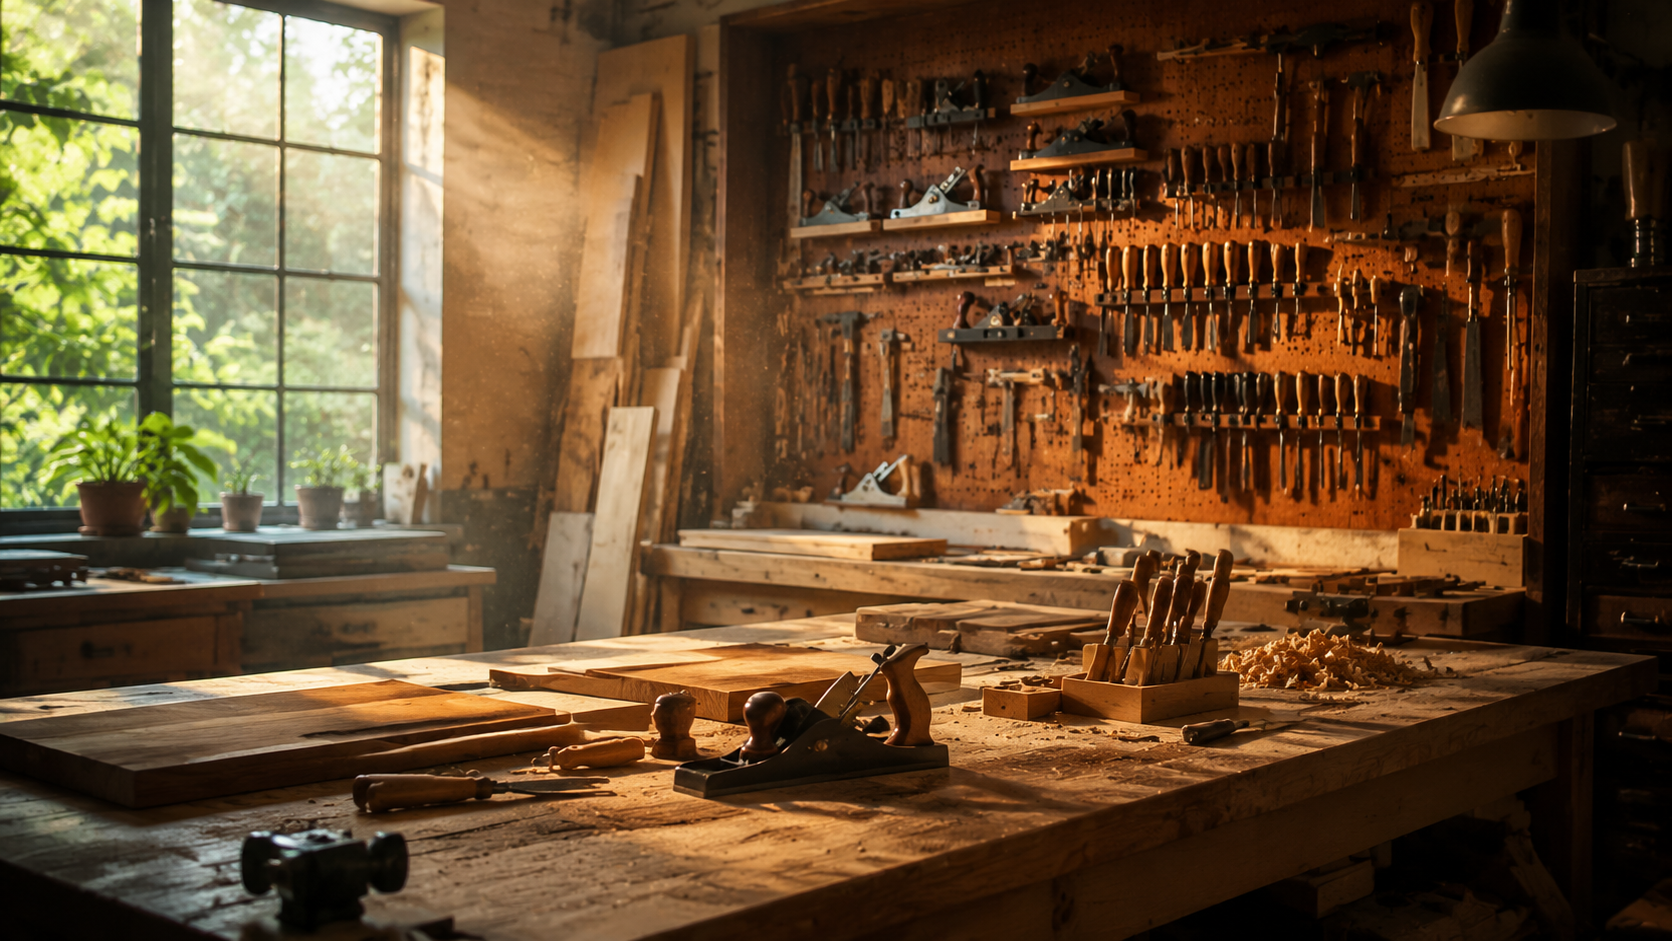
Create a cinematic establishing shot of a modern woodworking workshop interior, with a large window on the left casting warm afternoon light across a workbench, neatly arranged hand tools on a pegboard wall, and fine sawdust drifting in the light beams. Wide-angle composition with clear foreground-to-background depth, natural color grading, editorial cinematography style, 16:9 framing, 8K detail, no text.
Why Fanch AI Fits the Workflow
Whether you're building a long AI video or a single hero frame, the visual reference comes first. Fanch AI gives you a dedicated image model you direct with precise prompts — so you can lock a look, a wardrobe, and a lighting scheme before a second of AI video is generated. Good continuity starts with good stills, and a reference frame you control is the cheapest insurance an AI video project can buy.
👉 Start here: GPT Image 2 on Fanch AI — create the frames your AI video needs.