
A New AI Video Benchmark Says Quality and Safety Split the Field
A new AI video benchmark out of Hong Kong has produced a result that is awkward for everyone. The evaluation, published by the business school at the University of Hong Kong, reports that Chinese video models now lead on visual quality — Seedance 2.0 Pro finishing top on generation capability ahead of Veo 3.1 and Sora 2 Pro — while the same models trail on safeguards.
That combination is why this AI video benchmark is worth more than a headline. It is the first widely reported evaluation that measures quality and safety in the same frame, and the two halves of this AI video benchmark point in opposite directions.
What the HKU Report Found
Three findings carry this AI video benchmark.
Generation quality has flipped. In this AI video benchmark, the leading Chinese model outscored the leading US models on visual generation. That reverses the assumption most people carried into 2026, when Veo and Sora were treated as the ceiling — an assumption this AI video benchmark no longer supports.
Safeguards did not flip with it. The same AI video benchmark found the Chinese models weaker on safety and defensive measures — the report's own framing, as reported by Hong Kong media, is a tendency to emphasise quality while going light on defence.
The gap is a trade-off, not an accident. Read together, the results describe models optimised hard for output and less hard for refusals. That is a product decision, and an AI video benchmark that measures both is the only way to see it.
Why a Business School Ran This Benchmark
The provenance matters for how much weight to give it. This is not a computer-science lab measuring PSNR on a synthetic dataset. It came from HKU's business school, which shapes both the questions and the answers: capability, product-level behaviour, and the defensive posture a company would care about.
That makes the AI video benchmark more useful to buyers than to researchers. It answers "which model performs, and what does it refuse to do" rather than "which architecture wins on loss".
It also sets a limit. A single-institution evaluation with its own rubric is one strong data point, not a settled ranking. There is no peer-reviewed paper behind this AI video benchmark yet, and the prompt suite, scoring weights, and model versions are all choices the authors made.
What "Safeguards" Means for a Video Model
Safety in text models is a fairly clean question: does the model refuse the request? Video is messier, and that is exactly where an AI video benchmark earns its keep.
For a video model, the defensive half of an AI video benchmark covers several different things. Whether it refuses obviously disallowed prompts. Whether it holds the line when a request is wrapped in innocent framing. Whether it degrades gracefully instead of producing something unusable. Whether known-problem categories — likeness, violence, sexual content — are handled consistently rather than probabilistically.
A model that scores brilliantly on visual fidelity and poorly on those behaviours is a specific kind of product: excellent for a professional who never pushes it, risky for a platform that exposes it to the public. An AI video benchmark that reports both numbers lets you make that call instead of guessing.
Read Any AI Video Benchmark With Care
Four caveats, and they apply to this one as much as to the vendor charts I have criticised before.
One study is one study. A single institution's AI video benchmark is strong evidence and weak proof. The methodology has not been replicated yet.
Rankings expire fast. No AI video benchmark survives a quarter intact, and Veo 3.1, Sora 2 Pro and Seedance 2.0 Pro are all recent releases with successors already in flight. Any AI video benchmark is a photograph of a moving object.
"Visual quality" is a construct. It depends entirely on what the rubric rewards — motion coherence, texture, lighting, prompt adherence, or human preference. Two reasonable AI video benchmark designs can rank the same models differently.
Geography is not the variable. The useful reading of this AI video benchmark is not "Chinese models versus American models". It is "models tuned for output versus models tuned for refusal". The nationality is the story; the trade-off is the lesson, and that is what any AI video benchmark should be read for.
What This Means If You Generate Video
Practical consequences, if you take this AI video benchmark seriously.
Stop assuming the US models are the quality ceiling. The gap has closed, at least on visual output — that is the headline finding of this AI video benchmark. If you dismissed Seedance on quality grounds, retest.
Ask about refusals before you commit. An AI video benchmark scoring a model low on safeguards tells you something operationally useful: expect more friction on edge-case prompts, or less, depending on which way the score runs.
Pick per job, not per brand. A model that wins an AI video benchmark overall can still lose on your specific shot list. Together those three readings are the whole value of an AI video benchmark: it turns a brand argument into a shopping decision.
How to Run Your Own Small Benchmark
The most valuable response to someone else's AI video benchmark is a smaller one of your own. It takes about twenty minutes.
1. Fix five prompts. Cover the things you actually make: a person moving, a camera move, a texture close-up, a text-bearing surface, an abstract concept.
2. Fix the settings. Same aspect ratio, same duration, same seed where supported. Otherwise you are comparing settings, not models.
3. Score three things only. Prompt adherence, motion coherence, artefact count. Resist adding more axes; you will not keep them straight.
4. Watch at normal speed. Scrubbing hides motion failures, which is where AI video actually breaks.
5. Re-run quarterly. Every published AI video benchmark goes stale; yours will too.
Your five-prompt result will not be as comprehensive as the HKU AI video benchmark, and it will be far more useful to you, because it is measured against your work.
A Prompt to Try
If you are testing motion coherence, use a shot with one clear subject movement and one clear camera move — anything more and you cannot tell which part failed. That is the protocol any AI video benchmark uses, minus the sample size.
Copy & Paste this into Fanch AI (Model: gpt_image_2):
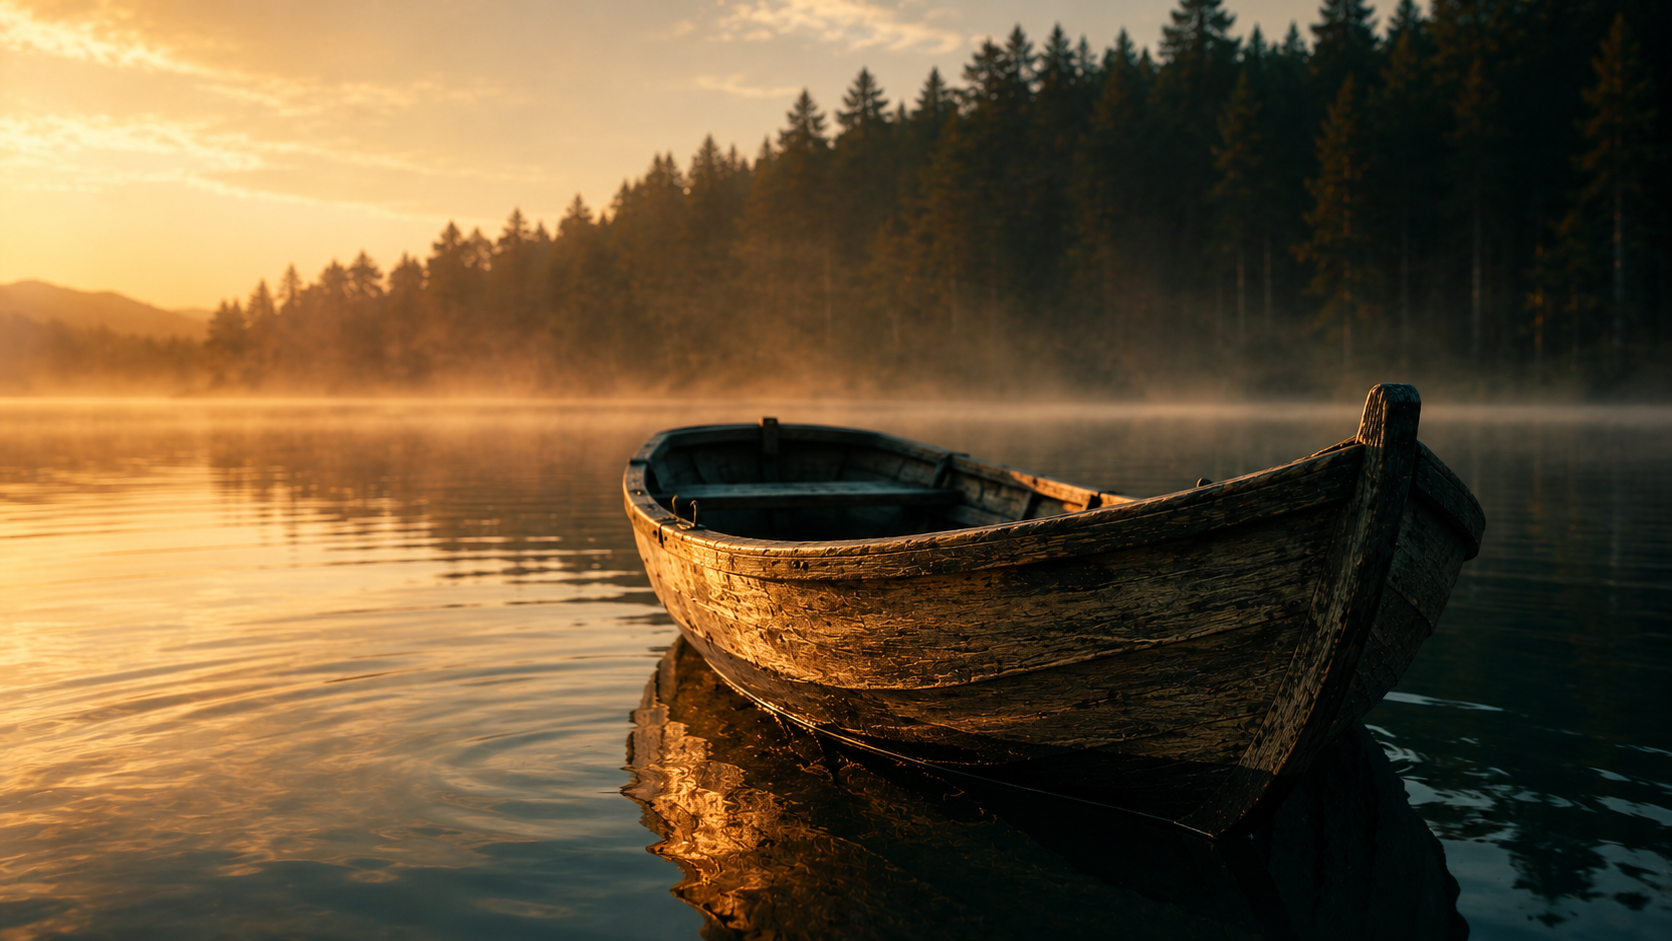
A cinematic still of a lone wooden rowboat drifting on a calm lake at golden hour, seen from a low angle just above the waterline: warm rim light along the hull, gentle ripples spreading outward, distant mist-covered pine treeline, soft haze in the air. Fine detail in the wet wood grain and water surface, shallow depth of field, warm amber and cool teal palette, 16:9 framing, 8K detail, no people, no text overlay.
Lock that frame, then push it into motion and watch what survives.
Why Fanch AI Fits
The lesson of a good AI video benchmark is that quality differences are now small enough that prompt craft decides the outcome. Fanch AI gives you a dedicated image model you direct with precise prompts, so you can settle composition and light on a cheap still before you spend on video generation — and compare models on a frame you actually control.